← All 50 books
Book 28 of 50 · Free
KPIs and Business Dashboards
25,184 words · 17 chapters · illustrated
Book 28 of 50 · Free
25,184 words · 17 chapters · illustrated
Book 28 of 50 — AstolixGen Learning Series For researcher and publication students
Every organization runs on numbers — but most organizations drown in numbers that do not help them decide anything. This book teaches you how to choose the small set of numbers that actually drive decisions: Key Performance Indicators (KPIs). You will learn what makes a KPI different from an ordinary metric, how to design KPIs from real business goals, how to tell leading indicators from lagging ones, how to break a KPI into its drivers with KPI trees, how to set targets and RAG thresholds, how to lay out a dashboard so people can read it at a glance, and how to build all of this in Power BI with DAX measures.
This is the detailed edition. It is written for MS/PhD students and early researchers who want more than surface definitions: real-world KPI examples across sales, operations, HR, education, healthcare, and finance; working DAX patterns you can copy into your own models; and a research lens on every chapter, because KPI design is itself a research activity — you define constructs, operationalize them, validate them against decisions, and iterate.
Learning objectives: By the end of this book, you will be able to
Organizations measure thousands of things: website visits, units produced, hours worked, calls answered, grades awarded. Only a handful of these measurements deserve the name KPI. The rest are ordinary metrics. The difference matters, because a dashboard full of ordinary metrics produces noise, while a dashboard of true KPIs produces decisions.
A Key Performance Indicator (KPI) is a measurement that tells you how well you are doing at something that matters to your strategy, compared against a target, so that you can decide what to do next.
Every word in that definition carries weight:
David Parmenter, whose book on KPIs is one of the standard references in this field, makes a sharp distinction that is worth learning early. He divides performance measures into four layers:
You do not have to adopt Parmenter's strict rules wholesale — in practice, most organizations do track financial KPIs like revenue and margin. But his taxonomy teaches the essential habit: not every number is a KPI, and the word "key" is doing real work.
People use "metric," "measure," and "KPI" interchangeably, which causes endless confusion. Here is a clean hierarchy you can use:
Think of it as a ladder: measure → metric → KPI. Every KPI is a metric, but most metrics never become KPIs. A KPI is a metric that has been promoted — given a target, an owner, a review rhythm, and a decision attached.
A KPI is not just a number and a name. A professional KPI has a specification — a short document (often one page) that removes all ambiguity. The standard fields are:
| Field | What it answers | Example |
|---|---|---|
| Name | What is it called? | Order Fulfilment Cycle Time |
| Definition | Exactly what is counted? | Hours from order confirmation to dispatch scan |
| Formula | How is it calculated? | SUM(dispatch time − confirm time) ÷ order count |
| Unit | What units? | Hours |
| Data source | Where does the data come from? | Warehouse management system, table Shipments |
| Owner | Who is accountable? | Head of Logistics |
| Frequency | How often is it measured? | Daily, reviewed weekly |
| Target | What is "good"? | ≤ 24 hours |
| Thresholds | When do we worry? | Green ≤ 24h, Amber 24–36h, Red > 36h |
| Related goal | Which strategy does it serve? | "Deliver faster than competitors" |
| Action on red | What happens when it fails? | Root-cause review within 48 hours |
If you cannot fill in most of these fields, you do not have a KPI yet — you have a vague wish. Chapter 3 walks through building this specification step by step.
E-commerce: Conversion rate = orders ÷ website sessions. Target 3.2%. Owner: Head of Digital. A drop below 2.8% triggers a checkout-funnel review. Note the comparison to target and the attached action — that is what makes it a KPI rather than a metric.
Manufacturing: OEE (Overall Equipment Effectiveness) = Availability × Performance × Quality. A world-class target is 85%. Owner: Plant Manager. OEE below 70% triggers a maintenance and downtime review.
Healthcare (hospital): Average patient wait time in emergency — from triage to first doctor contact. Target ≤ 30 minutes. Owner: Emergency Department Head. Breaches trigger staffing reviews.
Higher education: On-time graduation rate = students completing within the standard duration ÷ cohort size. Owner: Dean. A falling rate triggers curriculum and advising reviews.
Banking: NPL ratio (non-performing loan ratio) = bad loans ÷ total loans. Regulator and board watch this; above the internal limit triggers credit-policy tightening.
Telecom: Monthly churn rate = subscribers lost ÷ subscribers at start of month. Target < 2%. Owner: Chief Marketing Officer. A spike triggers retention-campaign analysis.
Notice the pattern in every example: number + target + owner + decision. That is the KPI signature.
In Power BI, a KPI lives as a DAX measure — a calculation that responds to filters and slicers. Here are the simplest building blocks. (Chapter 8 goes deep; this is your first taste.)
A basic actual-value measure:
Total Revenue = SUM ( Sales[Amount] )
A conversion-rate style ratio:
Conversion Rate =
DIVIDE (
    COUNTROWS ( Orders ),
    COUNTROWS ( Sessions )
)
DIVIDE is used instead of / because it safely returns blank instead of an error when the denominator is zero — exactly what you want on a dashboard.
A simple target-attainment measure, assuming a Targets table with a target amount:
Revenue Attainment % =
DIVIDE (
    [Total Revenue],
    SUM ( Targets[TargetAmount] )
)
Format this measure as a percentage in the model, and you have the core of a KPI card: actual, target, and attainment.
Newcomers often confuse KPIs with neighboring concepts. Clearing this up now prevents design errors later:
A KPI is born, lives, and should be allowed to die. The lifecycle:
Most organizations manage stages 1–5 and ignore 6–7, which is how dashboards accumulate dead KPIs. Put lifecycle stage in your KPI dictionary (Chapter 9) and review it explicitly.
There is an old joke about a drunk searching for his keys under a streetlight — not because he lost them there, but because the light is better. Organizations do this constantly: they KPI-ify whatever their systems already count (logins, tickets closed, hours logged) while the things that actually drive strategy (trust, quality, learning) go unmeasured because they are harder to capture.
The streetlight effect produces KPI sets that are precise but irrelevant. The defense is built into the design process: Step 1 (Chapter 3) starts from the goal, not from the database. When a candidate KPI is proposed, ask: "Are we choosing this because it matters, or because the data was already there?" If the right indicator is hard to measure, the honest options are: invest in measuring it (surveys, sampling, manual audits — all legitimate data sources), or admit the gap explicitly rather than filling it with a convenient proxy that misleads. A documented measurement gap is better than a confident wrong number.
For your research: Treat every construct in your thesis the way this chapter treats a KPI. A research construct like "student engagement" is vague until you give it a definition, a formula (how you compute it from data), a data source, and a measurement frequency — the same specification table as above. Reviewers reject papers whose key variables are defined loosely. If you can write a KPI specification, you can write an operational definition section that reviewers respect. Try it: pick one variable from your research and fill in the ten-field KPI table for it.
Key takeaways:
- A KPI is a strategic metric with a target, an owner, and a decision attached. A number without those is just a metric.
- The ladder is measure → metric → KPI; "key" is earned, not assumed.
- Every professional KPI has a specification: definition, formula, source, owner, frequency, target, thresholds, and action.
- In Power BI, KPIs are implemented as DAX measures — SUM, DIVIDE, and attainment ratios are your starting tools.
There is a famous trap in measurement: numbers that make you feel good but change nothing. Eric Ries, writing about startups, called these vanity metrics — metrics that look impressive in a presentation but give you no guidance about what to do next. Total registered users, total page views, total downloads: they almost always go up, they impress investors, and they are nearly useless for decisions. The antidote is the actionable metric: a number tied to a decision, where a change in the number tells a specific person to do a specific thing.
This chapter teaches you to tell the two apart — and to design KPIs that survive contact with reality.
A metric is actionable if you can answer three questions:
Run any candidate KPI through this test. "Monthly active users" passes if the Head of Product reviews it weekly and a 5% drop triggers a feature-usage investigation. "Total app downloads since launch" fails: nobody owns a decision based on it, and it can never go down.
The classic SMART framework, applied to KPI design:
Add one more letter that practitioners use: make it SMART-A, where A stands for Actionable — someone must be able to act on it. Or use the version from this book: every KPI must pass both SMART and the three-question actionability test.
SaaS software: - Vanity: Total registered accounts (always rises; includes dead accounts). - Actionable: Weekly active paying teams with a target and an owner; a drop triggers a churn-risk review.
E-commerce: - Vanity: Total page views (bots, accidental clicks, and one loyal customer reloading all count the same). - Actionable: Checkout conversion rate by device, because a drop on mobile specifically tells the team to inspect the mobile checkout.
University / education: - Vanity: Total enrolled students (a headcount that mixes full-time, part-time, and inactive). - Actionable: First-year retention rate by faculty — a drop in Engineering specifically triggers an advising intervention there.
Manufacturing: - Vanity: Total units produced (more units of defective product is not success). - Actionable: First-pass yield % — the share of units passing quality checks without rework. A drop triggers a line inspection.
Healthcare: - Vanity: Total patients seen (volume without outcomes can hide harm). - Actionable: 30-day readmission rate for cardiac patients — a rise triggers a discharge-process review.
HR: - Vanity: Total training hours delivered (hours do not equal learning). - Actionable: Post-training competency pass rate at 90 days — a fall triggers curriculum revision.
The pattern: vanity metrics are totals and aggregates that flatter; actionable KPIs are rates, ratios, and segmented numbers tied to a decision.
KPI overload. The dashboard with 80 "KPIs." When everything is key, nothing is. Research and practice converge on a small number: a team should actively manage roughly 5–10 KPIs; an executive dashboard shows fewer. The rest belong in detailed reports, not on the KPI wall.
Gaming and Goodhart's Law. Economist Charles Goodhart observed that "when a measure becomes a target, it ceases to be a good measure." Call-center agents measured on average call duration hang up on complex cases. Sales teams measured on revenue booked offer ruinous discounts at quarter-end. Salespeople measured on calls made log fake calls. Design KPIs in pairs that check each other: measure revenue and discount rate; measure calls and conversion. Chapter 5's KPI trees are the structural defense against gaming.
Perverse incentives from lagging-only KPIs. If you only measure results (profit, grades, deliveries), people optimize the result and damage the process. Balance every lagging KPI with a leading indicator (Chapter 4).
The "so what?" KPI. A number reported for years that nobody acts on. Audit your KPI set annually: for each KPI, ask the owner what decision it changed last quarter. If the answer is "none," retire or redesign it.
Incomparable definitions. Two regions computing "customer" differently, then comparing. The KPI specification from Chapter 1 (definition, formula, source) exists precisely to prevent this.
Good DAX anticipates decisions. Instead of a bare total, build measures that compare, segment, and flag:
Active Paying Teams =
CALCULATE (
    DISTINCTCOUNT ( Subscriptions[TeamID] ),
    Subscriptions[Status] = "Active",
    Subscriptions[Plan] <> "Free"
)
A week-over-week change that an owner can react to:
Active Teams WoW % =
DIVIDE (
    [Active Paying Teams]
        - CALCULATE (
            [Active Paying Teams],
            DATEADD ( 'Date'[Date], -7, DAY )
        ),
    CALCULATE (
        [Active Paying Teams],
        DATEADD ( 'Date'[Date], -7, DAY )
    )
)
And a flag measure that turns a number into a decision trigger:
Churn Risk Flag =
IF (
    [Active Teams WoW %] < -0.05,
    "Investigate",
    "Normal"
)
A dashboard that shows "Investigate" next to a red card is worth more than a dashboard that shows a number and hopes someone notices.
Every KPI has a price: data collection, system integration, validation effort, dashboard maintenance, and — the largest hidden cost — management attention spent reviewing it. A KPI that costs $20,000 a year in analyst time to produce but never changes a decision has negative value.
Before approving a KPI, estimate its total cost of measurement versus its expected decision value. Decision value is admittedly hard to quantify, but you can bound it: "If this KPI lets us catch one bad production batch per quarter, it saves ~$50,000." If no one can articulate a decision worth more than the measurement cost, the KPI fails the economic test — even if it passes SMART.
This is also the argument for retiring KPIs aggressively. The marginal dashboard slot is not free: every additional KPI dilutes attention for the others. Annual KPI audits (Chapter 9) should ask not just "is this still useful?" but "is it worth its cost?"
A mid-sized retailer launched a social media program and chose total followers and total likes as its KPIs, with a target of 100,000 followers in a year. The marketing agency hit the target in eight months — through giveaway campaigns attracting bargain-hunters who never bought anything. Follower count: green. Revenue from social: flat. The dashboard celebrated while the business learned nothing.
The redesign applied this chapter's tests. Owner: Head of E-commerce. New KPIs: social-attributed conversion rate (target 2.5%) and revenue per social session (target $1.80), each with the actionability test passed — a drop triggers a content and audience review. Followers stayed on a secondary report as a diagnostic metric, stripped of KPI status and its target. Within two quarters, the team had killed two underperforming campaigns the old dashboard would have called successes.
The moral generalizes: whenever a KPI can be improved without improving the business, it is not a KPI — it is a game. Design the set so that the only way to move the number is to do the real work.
Many product organizations rally around a single North Star metric — the one number that best captures the core value delivered to customers (e.g., for a marketplace: completed transactions; for a learning platform: weekly learners completing a lesson). The North Star is not a KPI for one team; it is the shared direction for all teams.
The pattern that makes it work: the North Star sits at the top of a constellation of input metrics, one per team — which is simply a KPI tree (Chapter 5) with an inspiring name. Marketing owns acquisition inputs, product owns activation and engagement inputs, support owns retention inputs. Each team's KPIs must demonstrably move the North Star (the validation discipline from Chapter 4 applies).
Two warnings. First, a North Star without counterbalances invites the same gaming as any single KPI — pair it with quality and sustainability metrics. Second, the North Star must be a customer-value metric, not a company-value metric: "revenue" is what the company gets; "successful projects delivered" is what the customer gets. Choose the customer's side, and revenue follows — that causal claim, of course, should be backtested like any leading indicator.
Guidelines from practice: an executive scorecard carries 5–8 KPIs; a departmental dashboard 8–12; an operational team board up to 15 including leading indicators. Beyond that, attention fragments and the review meeting becomes a read-out nobody absorbs.
When stakeholders demand "just one more KPI," use the substitution rule: to add one, nominate one for retirement. This forces the prioritization conversation that KPI overload otherwise avoids. And remember the hierarchy: the 6 KPIs on the executive page are supported by 30 diagnostic metrics on detail pages — the metrics are not deleted, they are demoted to where they belong. Scarcity at the top, abundance underneath.
For your research: Vanity metrics have an academic twin: vanity citations and vanity variables. A thesis that reports twenty descriptive statistics with no hypothesis attached is the research equivalent of a dashboard full of vanity metrics. For every table and figure in your thesis, apply the actionability test in research form: (1) Which research question does this answer? (2) What conclusion changes if this number were different? (3) Could a reviewer cut it without losing anything? If an analysis fails the test, it is decoration — cut it or connect it. Supervisors and reviewers notice the difference between a thesis that measures and a thesis that argues.
Key takeaways: - Vanity metrics flatter; actionable KPIs decide. Test every KPI with: who owns it, what decision it changes, and whether it can move both ways. - SMART plus actionability is the minimum design bar for any KPI. - Watch for the anti-patterns: KPI overload, gaming (Goodhart's Law), lagging-only sets, "so what?" numbers, and incomparable definitions. - Design KPIs in counterbalancing pairs, and let DAX compute the decision trigger — not just the number.
KPIs fail most often not in the dashboard, but at the whiteboard — when a team picks numbers before agreeing on goals. This chapter gives you a repeatable design process: seven steps that take you from a strategic goal to a signed-off, measurable, governed KPI. Follow it once for a real KPI and you will never again accept a number that someone invented in a meeting.
Start with the strategic goal the KPI must serve, and write it as an outcome, not an activity. "Launch a marketing campaign" is an activity. "Become the most trusted supplier in our region" is an outcome. Push until the goal names a result in the world.
A useful technique is the "so that" chain: keep asking "so that what?" until you reach the outcome that matters. "We want faster delivery" → so that? → "customers choose us over competitors" → so that? → "we win and keep more contracts." The KPI belongs at the end of the chain: contract win rate or customer retention rate.
If the goal is vague, the KPI will be vague. Spend half your design time here; it is the highest-leverage step.
For the goal, list the 3–5 critical success factors (CSFs): the things that must go right for the goal to happen. For "become the most trusted supplier," CSFs might be: on-time delivery, consistent product quality, responsive problem resolution, and transparent communication.
CSFs are still not numbers — they are conditions. The discipline is to keep them few. If you list fifteen CSFs, you have not prioritized; go back and force-rank.
For each CSF, brainstorm candidate indicators — as many as you like at this stage. For "on-time delivery," candidates include: on-time shipment %, average delay hours, % of orders delivered within the promised window, number of late-delivery complaints. Quantity first, judgment later. Involve the people who do the work, not just managers: operators know which numbers reflect reality and which are fiction.
Score each candidate against the tests from Chapters 1 and 2:
A simple scoring sheet (1–5 per criterion) makes the selection defensible. Keep the winners few: one or two KPIs per CSF, five to ten per team or business unit.
The Balanced Scorecard (Kaplan & Norton) is the classic framework for checking balance: look at your KPI set through four perspectives — Financial (how we look to shareholders), Customer (how customers see us), Internal processes (what we must excel at), and Learning & growth (how we improve and innovate). A set with ten financial KPIs and nothing on learning is not balanced; it is a bet that today's capabilities last forever.
For each selected KPI, complete the ten-field specification from Chapter 1: name, definition, formula, unit, data source, owner, frequency, target, thresholds, related goal, and action on red. This document is the contract between the KPI's consumers and its builders. Two rules:
Map each spec field to reality: which table, which column, what refresh cadence, what data-quality checks. Build a prototype dashboard with real data — even if ugly — and show it to the owner. Owners routinely discover at this stage that the definition does not match their mental model ("I meant confirmed orders, not placed orders"). Cheaper to fix now than after launch.
Validate the numbers against a known source: does the dashboard's monthly revenue match finance's reported figure? If not, find out why before anyone makes a decision on the dashboard.
A KPI is not finished at launch. Put each KPI on a review calendar:
Strategies change; KPI sets must change with them. A KPI that survives past its usefulness becomes a vanity metric with tenure.
Goal: "Enroll a strong, diverse incoming class that succeeds." CSFs: attract qualified applicants; convert admitted students; ensure admitted students are prepared. Candidates for "convert admitted students": yield rate (enrolled ÷ admitted), yield by scholarship band, melt rate (deposits who never show up). Selection: yield rate wins — actionable (owner: Director of Admissions; a drop triggers outreach review), data available, moves both ways. Spec: Yield Rate = enrolled headcount ÷ admitted headcount, per admission cycle, source: student information system, target 32%, thresholds green ≥ 32 / amber 28–32 / red < 28, action on red: conversion task-force within two weeks. Prototype: validated against the registrar's official census count. Review: termly.
A well-designed KPI often needs filtered or conditional measures. Examples from the admissions case:
Yield Rate =
DIVIDE (
    DISTINCTCOUNT ( Enrollments[StudentID] ),
    DISTINCTCOUNT ( Admissions[StudentID] )
)
Melt rate (deposits that never enrolled) — a counterbalancing KPI so the team cannot game yield by pressuring weak deposits:
Melt Rate =
DIVIDE (
    COUNTROWS (
        FILTER (
            Deposits,
            ISBLANK ( RELATED ( Enrollments[StudentID] ) )
        )
    ),
    COUNTROWS ( Deposits )
)
And a preparedness KPI from a related table:
Avg Entry Test Score =
AVERAGE ( Admissions[EntryTestScore] )
Notice how each measure mirrors a line in the KPI specification — definition, formula, source. When the spec is precise, the DAX writes itself; when the DAX is hard to write, the spec was vague.
Steps 1–4 work best as a facilitated workshop, not as homework. A practical format:
The workshop's hidden product is alignment: when the Head of Sales and the Head of Logistics argue about the definition of "on-time" in the room, you get one definition. When they do not, you get two dashboards that disagree forever.
Candidates for the CSF "deliver reliably," scored 1–5 on Actionable / Measurable / Gaming-resistant / Balanced-fit:
| Candidate | Act. | Meas. | Game-res. | Fit | Total |
|---|---|---|---|---|---|
| On-time delivery % | 5 | 5 | 4 | 5 | 19 |
| Avg delay hours | 4 | 5 | 4 | 4 | 17 |
| # of late complaints | 3 | 3 | 2 | 3 | 11 |
| Carrier's own SLA score | 2 | 4 | 2 | 2 | 10 |
On-time delivery % wins and becomes the KPI; average delay hours becomes a diagnostic metric on the operational page; complaints stay in the support system. The scoring sheet makes the decision explainable months later — "we chose X over Y because…" — which is exactly what auditors, new managers, and thesis examiners want to see.
Between the signed-off spec (Step 5) and the working dashboard (Step 6) sits the most failure-prone handoff in the whole process: the analyst must translate business language into tables and columns. De-risk it with a handoff document — one page per KPI containing:
Walk through the handoff with the data steward and sign it. Half of all "the dashboard is wrong" incidents are really "the analyst guessed at an ambiguous definition" — and this page is where the guessing stops.
For your research: The seven-step KPI design process is a template for designing your research methodology. Map it: Step 1 (clarify the goal) = your research objectives; Step 2 (CSFs) = the factors your literature review says matter; Step 3 (candidates) = candidate variables and instruments; Step 4 (evaluate) = your criteria for choosing variables — validity, reliability, data availability; Step 5 (specification) = your operational definitions chapter; Step 6 (prototype) = your pilot study; Step 7 (review) = your limitations and future-work section, where you retire measures that did not work. Examiners love a methodology chapter that shows this kind of explicit, auditable decision trail.
Key takeaways: - KPI design is a seven-step process: clarify goal → identify CSFs → brainstorm candidates → evaluate → specify → prototype → review and retire. - Half the work is Step 1: a vague goal guarantees a vague KPI. - Use the Balanced Scorecard's four perspectives to check that your KPI set is not lopsided. - The KPI specification is a contract — precise enough for a stranger to reproduce the number. - Every KPI needs a review calendar and permission to be retired.
Imagine driving a car by looking only in the rear-view mirror. That is what an organization does when it manages by lagging indicators alone: revenue, profit, graduation rates, annual customer satisfaction. These numbers tell you where you have been with complete accuracy — and give you no time to change where you are going. Leading indicators are the windshield: harder to read, less certain, but they show the road ahead while you can still steer.
The relationship is causal — or at least believed to be: leading indicator → (time passes, actions happen) → lagging result. The entire art is choosing leading indicators whose causal link to the lagging outcome is real, not wishful.
A lagging-only KPI set is an autopsy kit: it explains failures beautifully after they are irreversible. A leading-only set is a weather forecast: full of predictions nobody is accountable for achieving. Healthy organizations pair them:
| Lagging (the result we want) | Leading (what we manage weekly) |
|---|---|
| Quarterly revenue | Pipeline coverage ratio (pipeline ÷ quota) |
| Annual staff turnover | eNPS pulse score, 1:1 meeting completion |
| Customer churn (monthly) | Support ticket backlog, onboarding completion |
| Exam pass rate | Assignment submission rate, attendance |
| Machine downtime | Preventive-maintenance completion, vibration alerts |
| On-time delivery % | Orders picked per hour, carrier booking lead time |
The pairing rule: for every lagging KPI, name at least one leading indicator you will manage to move it. If you cannot name one, you do not have a management plan for that KPI — you have a hope.
The danger of leading indicators is false causality. A team declares "social media followers" a leading indicator of revenue because both go up over time — but followers may be bought, irrelevant, or simply correlated through a third cause (a growing marketing budget drives both). Three checks before trusting a leading indicator:
If a leading indicator fails these checks, it is a vanity metric wearing a windshield costume.
Sales: Pipeline coverage = total pipeline value ÷ quarterly quota. Healthy coverage is typically 3×–4× quota (because only a fraction closes). Owner: Sales Director. Action: below 3×, add prospecting sprints. Lagging partner: booked revenue.
Operations: Preventive maintenance compliance = scheduled PM tasks completed on time ÷ scheduled. A drop predicts breakdowns weeks later. Lagging partner: unplanned downtime hours.
HR: Manager 1:1 completion rate — teams whose managers skip 1:1s show higher attrition two quarters later in many workforce studies. Lagging partner: regretted attrition %.
Education: Week-4 assignment submission rate predicts final pass rates with depressing reliability; early non-submitters are the at-risk list. Lagging partner: course completion rate.
Healthcare: Hand-hygiene compliance % (audited) leads hospital-acquired infection rate. Lagging partner: infection rate per 1,000 patient-days.
Finance: Days sales outstanding (DSO) trend leads cash-flow stress. Lagging partner: operating cash flow.
Leading and lagging indicators need different review rhythms, because they move on different clocks:
A common dashboard mistake is putting both on the same monthly page and reviewing them with the same urgency. Instead, design two layers: an operational dashboard (leading, weekly, for managers) and a strategic dashboard (lagging, monthly/quarterly, for executives). Chapter 7 shows how to lay these out.
Pipeline coverage — a classic leading indicator:
Pipeline Coverage =
DIVIDE (
    CALCULATE (
        SUM ( Opportunities[Amount] ),
        Opportunities[Stage] <> "Closed Lost",
        Opportunities[Stage] <> "Closed Won"
    ),
    [Quarterly Quota]
)
A lagging partner with prior-period comparison:
Booked Revenue QoQ % =
DIVIDE (
    [Total Revenue]
        - CALCULATE (
            [Total Revenue],
            DATEADD ( 'Date'[Date], -1, QUARTER )
        ),
    CALCULATE (
        [Total Revenue],
        DATEADD ( 'Date'[Date], -1, QUARTER )
    )
)
And a simple early-warning flag combining both — the kind of measure that belongs on an operational dashboard:
Revenue Risk Flag =
IF (
    AND ( [Pipeline Coverage] < 3, [Booked Revenue QoQ %] < 0 ),
    "High risk",
    IF (
        [Pipeline Coverage] < 3,
        "Watch",
        "OK"
    )
)
The flag encodes the management logic: weak pipeline plus declining bookings is worse than either alone. This is how leading/lagging thinking becomes dashboard behavior.
Chapter 4 listed three checks (precedence, mechanism, track record). Here is how to actually run the third one — a backtest — with plain tools:
A worked sketch: pipeline coverage vs revenue with a 2-month lag, 18 months of data, lagged correlation r = 0.78 at lag 2, r = 0.41 at lag 0, stable across halves, and the March-collapse/May-fall episode checks out. Verdict: adopt as a leading KPI, review weekly, re-validate annually.
Even validated leading indicators break. Common failure modes:
The discipline: every leading indicator carries an expiry date — a scheduled re-validation in the KPI dictionary. Trust, but re-verify.
The operational dashboard — the weekly management tool for leading indicators — deserves its own design notes, distinct from the executive page:
For each lagging KPI you must manage, fill this canvas before choosing its leading partners:
| Field | Example |
|---|---|
| Lagging KPI & target | Booked revenue, 100% of quota |
| Expected lag | 60–90 days |
| Candidate leading indicator | Pipeline coverage |
| Causal mechanism (one paragraph) | Coverage → win rate × cycle: with a 25% win rate and 60-day cycle, 3× coverage mathematically yields ~quota; below 2.5× the math cannot work |
| Backtest result | r = 0.78 at 2-month lag, stable across halves |
| Owner & rhythm | Sales Director, weekly Monday review |
| Action on amber/red | Amber: add 2 prospecting sprints. Red: pipeline blitz week |
| Expiry / re-validate date | Re-validate after pricing change or annually |
One canvas per lagging KPI, filed in the KPI dictionary. It turns "we think this leads that" into an auditable, falsifiable claim — the management equivalent of a hypothesis with a pre-registered test.
For your research: Your thesis has leading and lagging indicators too, and naming them will make your methodology stronger. Lagging: your final results — accuracy, F1 score, statistical significance, the published paper itself. Leading: papers read per week, experiments completed, dataset cleaned, draft pages written. Most struggling researchers manage only the lagging indicators ("I must finish my thesis") and are surprised when the outcome arrives late. Set leading targets — e.g., "two experiments per week," "one related-work summary per day" — and review them weekly with your supervisor. In your methodology chapter, you can even frame pilot-study metrics as leading indicators of full-study success, which is a sophisticated move examiners appreciate.
Key takeaways: - Lagging indicators report outcomes; leading indicators predict them. You need both, paired deliberately. - Validate every leading indicator with temporal precedence, a causal mechanism, and back-tested track record. - Review leading indicators weekly (operational layer) and lagging indicators monthly/quarterly (strategic layer) — different clocks, different dashboards. - DAX can encode the pairing: pipeline coverage, QoQ change, and composite risk flags turn the concept into a working dashboard.
When revenue misses target by 8%, the executive asks the only question that matters: "Why?" A single KPI number cannot answer it. A KPI tree (also called a driver tree or value-driver tree) can — because it decomposes the headline number into the multiplicative or additive drivers that produced it, level by level, until you reach levers someone can actually pull.
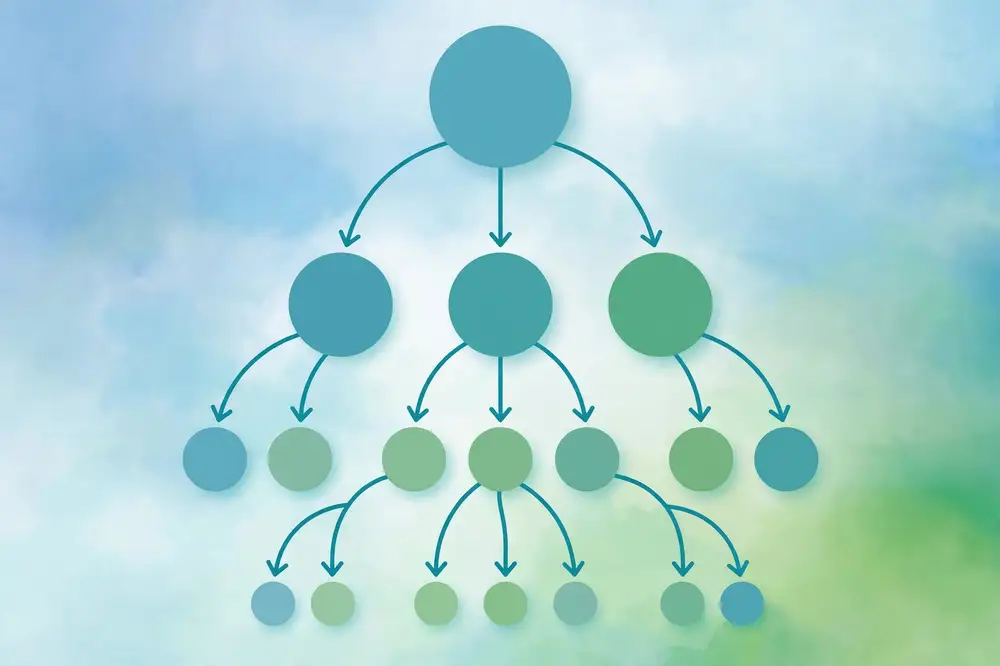
A KPI tree starts with one headline KPI at the top and breaks it into its mathematical components. Each branch is connected by an operator — usually × (multiplied) or + / − (added/subtracted). The tree keeps decomposing until the leaves are operational drivers: things a team can directly influence.
The classic ancestor is the DuPont analysis (developed for DuPont in the 1920s, still taught in every finance course):
ROE = Net Profit Margin × Asset Turnover × Equity Multiplier
Three drivers, each owned by different management actions: pricing and cost control (margin), operational efficiency (turnover), and financing decisions (leverage). One number, three conversations.
Top-level KPI: Revenue.
Level 1 — the fundamental decomposition of any transaction business:
Revenue = Number of Orders × Average Order Value
Level 2 — decompose each driver further:
Number of Orders = Sessions × Conversion Rate
Average Order Value = Items per Order × Average Item Price
So the full tree:
Revenue
├── Number of Orders
│   ├── Sessions (= Marketing spend × Cost efficiency, or organic + paid)
│   └── Conversion Rate (= f(checkout friction, trust, pricing))
└── Average Order Value
    ├── Items per Order (= f(cross-sell, bundling))
    └── Average Item Price (= f(product mix, discounting))
Now the "why" question becomes answerable: revenue missed by 8% → orders flat but AOV down 8% → items per order stable, average item price down → discounting was deeper than planned. The corrective action (tighten discount policy) is now obvious, and it took four levels of decomposition to find it.
Not all trees multiply. Profit decomposes additively:
Net Profit = Revenue − Cost of Goods Sold − Operating Expenses − Tax
And costs decompose further:
Operating Expenses = Payroll + Marketing + Rent + Utilities + Other
Additive trees are the natural home of variance analysis: for each leaf, compute actual vs budget, and the leaves with the largest unfavorable variances explain the headline miss. Finance teams have done this for a century; KPI trees bring the same discipline to non-financial KPIs.
SaaS: Recurring Revenue = Customers × ARPU (average revenue per user); Customers = New + Retained − Churned. Leaves: trial conversion rate, expansion revenue, churn rate — each owned by a different team (marketing, customer success).
University: Graduates = Intake × Retention Rate × Pass Rate; Retention = f(advising contacts, financial aid coverage, first-year experience score). Leaves point at specific interventions.
Hospital: Bed Occupancy Cost per Patient = Total Ward Cost ÷ Discharges; Total Ward Cost = Staff Cost + Supplies + Overhead. Variance at the supplies leaf triggers procurement review, not a general "cut costs" panic.
Manufacturing: OEE = Availability × Performance × Quality; Availability = (Planned Time − Downtime) ÷ Planned Time. The tree separates "machines stopped" from "machines ran slowly" from "machines made scrap" — three different fixes.
Rules for good trees:
Common failures: trees built from available data rather than causal logic (the "we had this column" tree); trees with 9 levels that nobody maintains; trees where two branches double-count the same driver; and the most common — a beautiful tree that is never connected to the actual dashboard, so variance analysis happens in spreadsheets once a quarter instead of continuously.
Decomposition in DAX means writing each node as a measure, then a variance measure per node:
Number of Orders = DISTINCTCOUNT ( Sales[OrderID] )

Average Order Value = DIVIDE ( [Total Revenue], [Number of Orders] )

Conversion Rate =
DIVIDE (
    [Number of Orders],
    DISTINCTCOUNT ( WebSessions[SessionID] )
)
Variance against target at any node — the engine of driver analysis:
Revenue Variance vs Target = [Total Revenue] - [Target Revenue]

AOV Variance vs Target = [Average Order Value] - [Target AOV]
In Power BI, the Decomposition Tree visual (built-in AI visual) automates this: drop Revenue in, add the driver fields, and users can click through levels interactively. For a governed KPI tree, though, prefer explicit measures like the above — they encode the approved definitions from the KPI spec instead of letting users invent ad-hoc splits.
A contribution measure shows which child explains the parent's variance:
Orders Contribution to Revenue Variance =
    ( [Number of Orders] - [Target Orders] ) * [Target AOV]
This is the math behind "orders explain −3% of the miss, AOV explains −5%."
A KPI tree explains structure; a bridge chart (waterfall) explains change over time. It starts at last period's value, then shows each driver's positive and negative contribution as floating bars, ending at this period's value. For the e-commerce example: start at last quarter's $4.2M revenue, +$300k from more sessions, −$180k from lower conversion, +$120k from higher AOV, ending at $4.44M.
The bridge is the executive's favorite variance visual because it reads like a sentence: "Revenue grew $240k, driven by traffic gains partly offset by weaker conversion." Build it in Power BI with the waterfall visual, feeding it the contribution measures from section 5.6. One caution: limit bridges to 5–7 bars — beyond that, aggregate small drivers into "other," or the story drowns in detail.
Not all drivers matter equally. Sensitivity analysis asks: if each driver moved by a realistic amount (±10%, or ±1 standard deviation), how much would the headline KPI move? The driver with the biggest impact per realistic move is where management attention belongs.
For Revenue = Orders × AOV: a 10% move in orders moves revenue 10%; a 10% move in AOV moves revenue 10% — symmetric here. But realistic moves differ: orders might swing ±15% seasonally while AOV moves ±4%. Multiply impact by realistic range: orders dominate. Present this as a simple table or tornado-style bar chart in the design review — it justifies why the team manages orders weekly and AOV monthly, and it stops arguments about which driver "matters more" with arithmetic instead of opinions.
Combine sensitivity with ownership: the highest-sensitivity driver should have the most senior owner and the tightest review rhythm. If your most sensitive driver has no owner, you have found your biggest organizational gap.
You have three implementation choices, with a clear recommended default:
Whichever you choose, the tree on screen must reconcile exactly like the tree on paper (Chapter 5, rule 1). Add a reconciliation check: a card showing Parent − Σ(children) that should read zero — if it ever doesn't, the model has a bug, and this card catches it before the executives do.
Targets vs actuals for Q3, e-commerce revenue tree (Revenue = Orders × AOV; Orders = Sessions × Conversion):
| Node | Target | Actual | Variance | Variance % |
|---|---|---|---|---|
| Revenue | $4,500k | $4,140k | −$360k | −8.0% |
| Orders | 90,000 | 90,000 | 0 | 0.0% |
| AOV | $50.00 | $46.00 | −$4.00 | −8.0% |
| Sessions | 3,000k | 3,103k | +103k | +3.4% |
| Conversion | 3.00% | 2.90% | −0.10pp | −3.3% |
Contribution analysis: orders variance (0) × target AOV ($50) = $0 contribution. AOV variance (−$4) × actual orders (90,000) = −$360k. The entire $360k miss is AOV. One more level: items per order held at 2.0 while average item price fell from $25.00 to $23.00 — discounting. Diagnosis complete in two drill steps: revenue missed because discounting deepened, not because traffic or conversion failed. The corrective action writes itself — and note how sessions actually beat target, a fact the headline −8% concealed.
For your research: A KPI tree is structurally identical to a conceptual framework in research — and to a regression model's decomposition of variance. When your thesis argues "X affects Y," you are asserting a driver relationship; a KPI tree forces you to name the intermediate nodes and the operators between them. Try drawing your research model as a KPI tree: top node = your dependent variable, branches = independent variables and mediators, leaves = measurable indicators. If the math does not reconcile (your indicators do not actually compose into the construct), your operationalization has a hole — better to find it now than at your defense. Several published papers in management science are essentially validated driver trees; framing yours that way is legitimate and legible to reviewers.
Key takeaways: - A KPI tree decomposes a headline KPI into drivers with explicit math (× or +/−) until it reaches ownable, actionable leaves. - The math must reconcile exactly; 3–4 levels is the practical depth. - Trees turn "revenue missed by 8%" into "discounting drove AOV down" — diagnosis, not just reporting. - In DAX, build each node as a measure plus variance measures; use explicit measures for governed trees.
A KPI without a target is a weather report: interesting, but no one knows whether to carry an umbrella. This chapter is about setting targets people believe in, defining the thresholds that turn numbers into red/amber/green signals, and implementing RAG status — the simplest, most misused visual language in dashboards.
In practice, most targets are set by one of three lazy methods: last year plus 10%, a round number someone liked, or whatever makes the budget balance. All three destroy credibility. Teams ignore targets they consider fictional, and once a target is ignored, the KPI attached to it dies too.
Defensible target-setting methods:
The professional move is to combine methods and document the rationale in the KPI spec: "Target 98% on-time delivery: historical 96.5%, benchmark median 97%, strategic requirement to lead the region → target 98% with stretch 99%." Anyone can audit that sentence.
A target is a single point; thresholds define the zones around it. The standard three zones:
Threshold design decisions:
RAG (Red–Amber–Green) works because it exploits pre-attentive vision: the eye finds the red dot before conscious reading begins. That power is why it is abused:
| KPI (direction) | Green | Amber | Red |
|---|---|---|---|
| On-time delivery % (higher better), target 98% | ≥ 98 | 95–<98 | < 95 |
| Defect rate % (lower better), target ≤ 1% | ≤ 1.0 | 1.0–2.0 | > 2.0 |
| Employee attrition % (lower better), target ≤ 8% | ≤ 8 | 8–12 | > 12 |
| Cash runway months (higher better), target ≥ 12 | ≥ 12 | 6–<12 | < 6 |
| Student pass rate % (higher better), target 85% | ≥ 85 | 75–<85 | < 75 |
| Server uptime % (higher better), target 99.9% | ≥ 99.9 | 99.5–<99.9 | < 99.5 |
The core pattern — attainment against target:
Revenue Attainment % =
DIVIDE ( [Total Revenue], [Target Revenue] )
RAG status for a higher-is-better KPI:
Revenue RAG =
VAR Attainment = [Revenue Attainment %]
RETURN
    SWITCH (
        TRUE (),
        ISBLANK ( Attainment ), "No data",
        Attainment >= 1, "Green",
        Attainment >= 0.95, "Amber",
        "Red"
    )
For a lower-is-better KPI, flip the comparisons:
Defect Rate RAG =
VAR Rate = [Defect Rate %]
RETURN
    SWITCH (
        TRUE (),
        ISBLANK ( Rate ), "No data",
        Rate <= 0.01, "Green",
        Rate <= 0.02, "Amber",
        "Red"
    )
In Power BI, apply conditional formatting by field value: create a companion measure returning hex colors and point the formatting at it:
Revenue RAG Color =
SWITCH (
    [Revenue RAG],
    "Green", "#2E7D32",
    "Amber", "#F9A825",
    "Red", "#C62828",
    "#9E9E9E"
)
Then use "Format by → Field value" on the KPI card's background or font color. This keeps the threshold logic in one governed measure instead of scattered across visual settings — change the threshold once, and every visual updates.
Targets are negotiated, not computed — and the negotiation has predictable pathologies:
The professional stance: be the analyst who brings the arithmetic — baseline, benchmark, driver plan — to every negotiation. Arithmetic does not eliminate politics, but it confines it to honest disagreements about assumptions.
For stable, high-frequency operational KPIs (defect rates, call handle times, daily throughput), consider control charts from statistical process control (Shewhart's method, nearly a century old and still the right tool):
This is threshold-setting with a statistical conscience: instead of arbitrary red bands, the process's own history defines "unusual." In Power BI, compute the mean and standard deviation in DAX and plot them as constant lines over the KPI trend. Use control limits for process KPIs; use target-based RAG for goal KPIs. The two answer different questions — "is the process stable?" vs "are we hitting the goal?" — and a mature operation asks both.
How targets are announced determines whether they motivate or demoralize. Write a one-page target memo per KPI (or per scorecard) containing:
Circulate before the period starts, discuss in person, invite challenge on the assumptions (not the ambition). Teams that helped stress-test the rationale defend the target later; teams that received it by email negotiate against it all year.
Not every KPI needs three zones. Use RAG bands (green/amber/red) for KPIs under active management — where amber's "prepare contingency" has real meaning (revenue, delivery, attrition). Use a single threshold (pass/fail) for compliance and constraint KPIs — SLA uptime, regulatory ratios, safety incidents — where anything below the line is simply a breach, and amber would only soften accountability. And use two-sided bands (green inside, amber/red outside either way) for KPIs where both extremes are bad: bed occupancy (Chapter 10), inventory days, meeting load. Choosing the wrong shape is a common silent error: RAG bands on a compliance KPI invite negotiation with a red line that should be absolute.
For your research: Targets and thresholds have a direct research analogue: hypotheses and significance thresholds. Your H1 ("X improves Y") is the target; your alpha level (p < 0.05) is the threshold that turns a result red or green. The lesson of this chapter applies: arbitrary thresholds destroy credibility. Justify your alpha, your effect-size thresholds, and your "practically significant" bands the way this chapter justifies KPI targets — from prior literature (benchmarking), from the problem's requirements (top-down), or from pilot data (historical baseline). A methodology section that says "we set the minimum meaningful effect at d = 0.3 because prior studies in this domain report d = 0.2–0.4" is the research version of a documented target rationale, and reviewers reward it.
Key takeaways:
- Set targets with defensible methods (baseline, benchmark, top-down, bottom-up, stretch) and document the rationale in the KPI spec.
- Thresholds define green/amber/red zones; calibrate width from history and state the higher/lower-is-better direction explicitly.
- RAG exploits pre-attentive vision — always pair color with the number, target, and variance, and never encode by color alone.
- Implement RAG in DAX with SWITCH(TRUE(),...) plus a hex-color companion measure, formatted by field value for single-point governance.
A dashboard is not a report. A report answers questions you already had; a dashboard lets you spot the questions you did not know to ask — in under five seconds. Stephen Few, the most-cited authority on dashboard design, defines a dashboard as "a visual display of the most important information needed to achieve one or more objectives, consolidated and arranged on a single screen so the information can be monitored at a glance." Every word matters: most important (not everything), single screen (no scrolling to find the reds), at a glance (pre-attentive, fast).
Design for a viewer who gives you five seconds. In those seconds they should grasp: are we OK, and if not, where? Everything else is drill-down.
Humans read screens in a predictable pattern (top-left first in left-to-right cultures, then across and down — the rough "F" or "Z" pattern). Place content accordingly:
Never make the viewer scroll to find bad news. If reds live below the fold, the dashboard has failed its primary job.
Pattern 1 — KPI card strip. A row of 4–6 cards across the top. Each card: KPI name, big current value, small target, variance (absolute and %), RAG indicator, 12-period sparkline. This is the executive summary of the dashboard. Keep cards uniform in size — varying sizes imply varying importance, which confuses the five-second scan.
Pattern 2 — RAG heatmap matrix. Rows = business units/regions/products, columns = KPIs, cells = RAG color + value. The eye instantly finds the red intersections: "the West region's delivery KPI is red." Ideal for multi-entity monitoring (retail chains, hospital wards, university faculties).
Pattern 3 — Trend + variance panel. For each headline KPI: a line chart of actual vs target over 12–13 periods, with the variance shaded. Answers "is this a blip or a trend?" — the question every executive asks after seeing a red card.
Pattern 4 — Decomposition panel. Bar chart of variance by driver (from the KPI tree): which product lines, regions, or cost categories explain the miss. Pair with the Decomposition Tree visual for interactive drill-down.
Pattern 5 — Exception list. A table sorted worst-first: top 10 negative variances, overdue actions, breached thresholds. This is the "Monday morning action list." Sort by impact (variance × size), not alphabetically.
Pattern 6 — Gauge (use sparingly). Few's famous guidance: gauges waste space — a bullet graph or a simple card with target marker communicates the same in a fraction of the pixels. If you must show "actual vs target," prefer a bullet graph: a bar for actual, a line for target, shaded bands for thresholds. One exception: audiences who genuinely expect dials (plant-floor displays) — match your users, not the textbook.
Executive dashboard (strategic, monthly): 5–8 headline KPIs, RAG, trends, exception summary. One page. The CEO should not need slicers to understand it.
Operational dashboard (weekly/daily): leading indicators, driver breakdowns, exception lists, filters by team/shift/region. More interactive — slicers and drill-through are expected because managers investigate.
Analytical deep-dive (ad hoc): the full KPI tree, variance tables, distributions. This is where analysts live; density is acceptable because the user is investigating, not scanning.
Mobile: Power BI's mobile layout view exists for a reason — a 12-column desktop dashboard is unreadable on a phone. Design a separate mobile layout: KPI cards stacked, one trend per KPI, exception list. Executives check dashboards on phones; if yours is broken there, it does not exist for them.
KPI cards need compact measures — value, target, variance in one visual. Build a small family per KPI:
-- Card: current value
Revenue = [Total Revenue]

-- Card: target
Revenue Target = [Target Revenue]

-- Card: variance (absolute)
Revenue Variance = [Total Revenue] - [Target Revenue]

-- Card: variance %
Revenue Variance % =
DIVIDE (
    [Revenue Variance],
    [Target Revenue]
)
For the trend panel, a target line needs a target that respects the date axis. If targets are stored monthly, ensure the relationship (or TREATAS) propagates the date filter:
Target Revenue (Date-aware) =
CALCULATE (
    SUM ( Targets[Amount] ),
    TREATAS ( VALUES ( 'Date'[YearMonth] ), Targets[YearMonth] )
)
And for the exception list, a measure that ranks problem areas by impact:
Region Revenue Shortfall =
VAR Shortfall = [Target Revenue] - [Total Revenue]
RETURN
    IF ( Shortfall > 0, Shortfall, BLANK () )
Sort the table by this measure descending — worst first, exactly as Pattern 5 demands. BLANK() hides regions that are on target, keeping the exception list clean.
Learn to recognize these in the wild — each is a real dashboard failure mode:
Never build the final dashboard first. The professional workflow:
Chapter 6 said never to encode status by color alone; here is how to do it properly:
Accessibility is not extra credit on a KPI dashboard — the executive who cannot distinguish your red from your green will make the wrong call, and that is a design failure with business consequences.
Use this checklist to review any dashboard — yours or someone else's — in a minute:
Score 1 point per yes. Anything below 7 goes back to the wireframe stage. Run this critique on your own capstone dashboard (Chapter 12) before presenting it.
For your research: Dashboard layout principles are figure-design principles for your papers. The five-second rule applies to every figure a reviewer sees: can they grasp the message before reading the caption? One idea per visual, declutter, consistent encoding, numbers with context (always show the baseline alongside your result) — these are the same rules that separate published figures from rejected ones. When you design your results section, lay it out like a dashboard: headline findings first (your "KPI cards" — the key result tables), then trends and comparisons, then detailed breakdowns in the appendix. Reviewers scan; make the scan rewarding.
Key takeaways: - Design for the five-second scan: headline KPI cards top-left, trends top-right, decomposition middle, exceptions bottom. Bad news never below the fold. - Use proven patterns: KPI card strip, RAG heatmap, trend+target panel, decomposition panel, exception list — and bullet graphs instead of gauges. - One idea per visual; consistent colors; declutter; every number shown with its comparison. - Build separate layouts for executives (monthly, simple), operators (weekly, interactive), analysts (dense), and mobile.
This is the chapter where KPIs become real. Everything so far — definitions, design, RAG — lives in Power BI as DAX measures. This chapter builds your complete KPI measure toolkit: the patterns professionals reuse in every model, with explanations of why each pattern works, not just the code. Copy them, adapt the table and column names, and understand each line before you use it.
Prerequisite: all time-intelligence patterns in this chapter require a proper date table — a continuous calendar table marked as a date table, related to your fact tables. Without it, DATESYTD, SAMEPERIODLASTYEAR, and DATEADD produce wrong or blank results. Build the date table first; it is the foundation every KPI measure stands on.
Every KPI family starts with two measures: the actual and the target.
Total Revenue = SUM ( Sales[Amount] )
Targets usually live in a separate table (one row per period per entity — e.g., per month per region). If Targets is related to the date table:
Target Revenue = SUM ( Targets[TargetAmount] )
If it is not related (common with Excel-based target files), bridge it with TREATAS:
Target Revenue =
CALCULATE (
    SUM ( Targets[TargetAmount] ),
    TREATAS ( VALUES ( 'Date'[YearMonthNumber] ), Targets[YearMonthNumber] )
)
Keep target logic in one measure per KPI. Every card, chart, and RAG rule in the model should reference [Target Revenue], never re-sum the targets table directly. Single point of truth.
Revenue YTD =
CALCULATE (
    [Total Revenue],
    DATESYTD ( 'Date'[Date] )
)

Revenue MTD =
CALCULATE (
    [Total Revenue],
    DATESMTD ( 'Date'[Date] )
)

Revenue QTD =
CALCULATE (
    [Total Revenue],
    DATESQTD ( 'Date'[Date] )
)
How it works: CALCULATE takes the base measure and re-evaluates it under a modified filter — here, the filter is "all dates from the start of the year/month/quarter through the latest date in the current filter context." That last phrase matters: YTD respects slicers, so selecting March shows Jan–Mar. For fiscal years starting in a month other than January, pass the year-end date: DATESYTD ( 'Date'[Date], "30/06" ) for a June year-end.
The same pattern gives YTD targets — essential for fair attainment:
Target Revenue YTD =
CALCULATE (
    [Target Revenue],
    DATESYTD ( 'Date'[Date] )
)

Revenue YTD Attainment % =
DIVIDE ( [Revenue YTD], [Target Revenue YTD] )
Never compare YTD actual against the full-year target — that classic error makes every KPI red until December.
Revenue PY =          -- same period last year
CALCULATE (
    [Total Revenue],
    SAMEPERIODLASTYEAR ( 'Date'[Date] )
)

Revenue Last Month =
CALCULATE (
    [Total Revenue],
    DATEADD ( 'Date'[Date], -1, MONTH )
)

Revenue Last Quarter =
CALCULATE (
    [Total Revenue],
    DATEADD ( 'Date'[Date], -1, QUARTER )
)
SAMEPERIODLASTYEAR shifts the current filter context back exactly one year (handles leap years and partial periods correctly). DATEADD shifts by any interval — the workhorse for month-over-month and rolling analyses.
Growth measures built on these:
Revenue YoY % =
DIVIDE (
    [Total Revenue] - [Revenue PY],
    [Revenue PY]
)

Revenue MoM % =
DIVIDE (
    [Total Revenue] - [Revenue Last Month],
    [Revenue Last Month]
)
Always use DIVIDE — in real data, prior periods are sometimes zero or blank (new products, new regions), and DIVIDE returns blank instead of an error that breaks the visual.
Variance (actual vs target) and variance %:
Revenue Variance = [Total Revenue] - [Target Revenue]

Revenue Variance % =
DIVIDE ( [Revenue Variance], [Target Revenue] )
For driver analysis (Chapter 5), write variances at each tree node and a contribution measure:
Orders Variance = [Number of Orders] - [Target Orders]

AOV Variance = [Average Order Value] - [Target AOV]

-- How much of the revenue variance comes from orders?
Orders Contribution =
    [Orders Variance] * [Target AOV]

-- ...and how much from average order value?
AOV Contribution =
    [AOV Variance] * [Number of Orders]
(These are first-order approximations that attribute the interaction term to AOV — document the choice in the measure description.)
Rolling 12-month revenue smooths seasonality — the number executives actually want for trend judgment:
Revenue Rolling 12M =
CALCULATE (
    [Total Revenue],
    DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ), -12, MONTH )
)
A 3-month moving average for noisy operational KPIs (hysteresis from Chapter 6, in code):
Defect Rate 3M Avg =
AVERAGEX (
    DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ), -3, MONTH ),
    [Defect Rate %]
)
AVERAGEX iterates the 3-month date set and averages the defect-rate measure in each month's context — correctly weighting by the measure's own logic rather than averaging raw rows.
Combine attainment with SWITCH(TRUE(),...) (Chapter 6 pattern), plus a numeric status for sorting:
KPI Status Score =
VAR Attainment = [Revenue YTD Attainment %]
RETURN
    SWITCH (
        TRUE (),
        ISBLANK ( Attainment ), 0,
        Attainment >= 1, 3,
        Attainment >= 0.95, 2,
        1
    )
The numeric score (3/2/1/0) lets you sort exception tables worst-first and lets conditional formatting use a numeric gradient — while the text RAG measure from Chapter 6 provides the human label.
Targets often exist at a coarser grain than actuals — annual targets but daily sales. Allocate carefully:
-- Annual target spread evenly across the year's days (simple allocation)
Daily Allocated Target =
DIVIDE (
    CALCULATE (
        SUM ( Targets[AnnualTarget] ),
        ALL ( 'Date' )
    ),
    365
)

Target To Date =
    [Daily Allocated Target]
        * COUNTROWS (
            DATESYTD ( 'Date'[Date] )
        )
Better: store targets at monthly grain and allocate by working days, or use a seasonality profile table. The principle: the allocation method is a design decision — document it in the KPI spec, because "target to date" changes with the method.
A KPI model with 200 measures named Measure 1…Measure 47 is unmaintainable. Professional habits:
[Total Revenue], [Revenue YTD], [Revenue Attainment %] — KPI name first, then the calculation. Suffixes (%, YTD, vs Target) sort related measures together.Most KPI measures are fully additive — summing daily revenue gives monthly revenue. But some of the most important KPIs are semi-additive: they sum across every dimension except time. Headcount, inventory levels, and account balances must not be summed across dates (adding January's headcount to February's is nonsense); you want the last value in the period.
Headcount =
CALCULATE (
    SUM ( HeadcountSnapshot[Employees] ),
    LASTDATE ( 'Date'[Date] )
)
LASTDATE returns the final date in the current filter context, so the measure picks up the headcount snapshot at period-end — correct for months, quarters, and years alike. The same pattern serves inventory and bank balances. Mark these measures clearly (a "Semi-additive" display folder) because every new analyst will try to sum them.
A related trap: averages of averages. "Average monthly headcount for the year" is not the average of twelve monthly averages unless every month has equal weight — compute it from the grain instead:
Avg Headcount (Year) =
AVERAGEX (
    VALUES ( 'Date'[Month] ),
    [Headcount]
)
Five traps that catch even experienced DAX authors:
CALCULATE that removed a needed filter. Debug by rebuilding the visual's filter context mentally — or with DAX Studio's query plans when serious.FILTER over full tables. CALCULATE ( [M], FILTER ( Sales, ... ) ) iterates every row of Sales. Prefer filtering small dimension tables and letting relationships propagate: CALCULATE ( [M], 'Product'[Category] = "X" ) — the engine does far less work.dax
Revenue YoY % =
VAR CurrentRevenue = [Total Revenue]
VAR PriorRevenue = [Revenue PY]
RETURN
DIVIDE ( CurrentRevenue - PriorRevenue, PriorRevenue )
Variables are evaluated once in their context — cleaner and often faster than repeating measures.COALESCE ( [M], 0 ) forces zero; leaving blank keeps the visual honest about gaps. Document the choice — it changes RAG behavior.Rule of thumb: correct first, fast second, clever never. A KPI measure must be auditable by the finance team — if only you understand it, it is a liability.
Not every organization runs on January–December. Retailers use 4-4-5 calendars; many firms start the fiscal year in July or October. Two techniques keep your KPIs correct:
Fiscal YTD with a custom year-end. Pass the year-end date to the time-intelligence functions:
Revenue FYTD =
CALCULATE (
    [Total Revenue],
    DATESYTD ( 'Date'[Date], "30/06" )   -- fiscal year ends 30 June
)
Every function in this chapter (DATESMTD, SAMEPERIODLASTYEAR, DATEADD) respects the date table's continuity — but you must keep the fiscal logic consistent: if FYTD uses June year-end, the target table's "YTD target" must too, or attainment compares mismatched periods.
Week-based analysis. Retail weeks (Sun–Sat or Mon–Sun) need a WeekNumber and YearWeek in the date table. A week-over-week measure:
Revenue WoW % =
VAR CurrentWeek =
    CALCULATE ( [Total Revenue], DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ), -7, DAY ) )
VAR PriorWeek =
    CALCULATE (
        [Total Revenue],
        DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ) - 7, -7, DAY )
    )
RETURN
    DIVIDE ( CurrentWeek - PriorWeek, PriorWeek )
Caution: partial weeks at period edges distort WoW — either compare complete weeks only or flag partial weeks in the visual. Document the week definition in the KPI spec; "week" is one of the most ambiguous words in business.
For your research: DAX measures are operational definitions in executable form — and that makes them a research artifact worth describing. If your thesis uses a Power BI dashboard (for example, to monitor an intervention, a survey rollout, or experimental data collection), your methodology chapter can present the key DAX measures exactly as this chapter does: definition, formula, and the design decision behind each (why YTD vs full-year target, why a 3-month average for noisy signals). Examiners in applied fields increasingly accept — and respect — computational appendices. Even without Power BI, the habit transfers: define every derived variable in your analysis with the same precision as a DAX measure, including how you handled edge cases (division by zero, missing periods). That is what separates reproducible research from "we computed the rates."
Key takeaways:
- Build KPI measures in families: base → target → YTD/MTD/QTD → prior period → variance → attainment → RAG. One measure per concept, referenced everywhere.
- Time intelligence needs a proper date table; CALCULATE + DATESYTD/SAMEPERIODLASTYEAR/DATEADD is the core pattern.
- Always compare YTD actual to YTD target; use DIVIDE to survive zero/blank denominators.
- Document allocation methods for coarse-grain targets, and keep measure hygiene: naming, folders, descriptions, format strings.
A dashboard nobody opens is a very expensive painting. KPIs create value only when the right person sees the right signal at the right time — and when everyone trusts the numbers enough to act on them. This chapter covers the two delivery mechanisms (alerts and subscriptions) and the unglamorous discipline that keeps the whole system honest: governance.
Data alerts (called "alerts" in the Power BI service) watch a KPI and notify you when it crosses a threshold you set — e.g., "alert me if daily revenue drops below $50,000." Key properties:
Best practices: alert on exceptions, not on everything — ten daily alerts become ten ignored emails. Alert on KPIs with a named owner and a defined response (Chapter 1's "action on red" field is the alert's runbook). Prefer rate-of-change or threshold-breach alerts over absolute values where seasons shift the baseline (alert on "attainment < 95%" rather than "revenue < $X" in December vs January).
The DAX side: build the alert condition as a measure so the logic is governed, then pin a card showing it:
Revenue Alert Trigger =
IF ( [Revenue YTD Attainment %] < 0.95, 1, 0 )
Pin this to a dashboard, set the alert to fire when the tile exceeds 0 — and the threshold logic lives in the model, versioned and documented, not in someone's alert settings.
Subscriptions email (or push) a snapshot of a report or dashboard on a schedule — daily at 7 AM, every Monday, first of the month. They serve a different need than alerts: alerts say "something is wrong now"; subscriptions say "here is the state of the world, routinely."
Design guidance:
Governance is everything that keeps KPIs defined once, computed once, trusted always. Its centerpiece is the KPI dictionary (also called a metric catalog or KPI registry): a single governed list of every approved KPI with its full specification (Chapter 1's ten fields), its DAX measure name, its owner, its refresh cadence, and its certification status.
Minimum viable governance for a small organization:
KPIs amplify data problems: a wrong number with a red background triggers real, costly actions. Build quality checks into the model:
-- Reconciliation: does the model agree with the source system?
Sales Row Count Check =
COUNTROWS ( Sales )

-- Freshness: when was data last loaded?
Data As Of =
MAX ( Sales[LoadDate] )

-- Completeness: are we missing recent days?
Missing Days (Last 30) =
VAR ExpectedDates =
    DATESINPERIOD ( 'Date'[Date], TODAY (), -30, DAY )
RETURN
    COUNTROWS ( EXCEPT ( ExpectedDates, VALUES ( Sales[OrderDate] ) ) )
Surface these on an admin page or in the report footer: "Data as of 7 Oct 2026 · 0 missing days." When a KPI looks wrong, the first question is always "is the data fresh and complete?" — answer it before the meeting starts.
Row-level security (RLS) is governance too: regional managers see only their region's KPIs. Define RLS roles on the dataset so one dashboard serves everyone without leaking other regions' numbers. Test RLS with "view as role" before publishing — a KPI system that shows the wrong person's data loses trust instantly and permanently.
Governance is not a document; it is a calendar:
Record decisions from every review. A KPI system with no decision log is a measurement hobby.
Once a year, put every KPI in the dictionary through this audit. Score pass/fail; failures go to the quarterly design review for redesign or retirement:
Publish the audit summary: KPIs kept, redesigned, retired, and proposed. Transparency here builds the trust that governance exists to protect.
Small organizations do not need a bureaucracy, but they do need named roles:
Write the RACI into the governance page of your KPI dictionary. When a number is disputed at 8 AM before a board meeting, the RACI tells you who decides — which is the difference between a ten-minute resolution and a three-day email war.
When a headline KPI goes red, the organization needs a practiced response, not improvisation. A runbook — one page per critical KPI, stored with the KPI dictionary — specifies:
Example: On-time delivery goes red on a Monday alert. Triage: data fresh, no single event — real deterioration. Diagnosis: driver tree shows carrier pickup failures in the West region, contributing −2.1pp. Action: logistics head switches West region to backup carrier for 2 weeks; deadline Wednesday. Follow-up: Monday review shows recovery to amber. Total time from red to action: 48 hours — because the runbook existed before the crisis.
For your research: Governance is the organizational version of research ethics and reproducibility practices — and thesis examiners probe exactly these areas. Map the concepts: the KPI dictionary = your codebook (every variable defined once, with source and computation); certification = validated instruments (pilot-tested, reliability-checked); change control = your research log (dated record of every methodological decision — why you changed a questionnaire item in week 3); refresh/quality SLAs = your data-quality checks (missing-data reports, outlier review); RLS = data anonymization and access control for participant data. When your methodology chapter describes these practices explicitly, it signals a researcher who thinks like a professional — and it preempts the examiner's hardest questions about trust in your numbers.
Key takeaways: - Alerts push exceptions ("something is wrong now"); subscriptions push routine state ("here is the world, on rhythm"). Use both, sparingly and matched to decision rhythms. - Governance = KPI dictionary, named owners, certification, change control, refresh/quality SLAs, and RLS. No dictionary, no official numbers. - Build data-quality measures (freshness, completeness, reconciliation) into the model and surface "data as of" on every dashboard. - Governance runs on a calendar: operational reviews weekly, tactical monthly, strategic quarterly, audit annually — with every decision logged.
KPI principles are universal, but KPI practice is local: each domain has its own rhythms, its own gaming risks, and its own classic KPI sets. This chapter tours four domains in depth — with full KPI sets, owners, targets, and DAX — so you can see the patterns from earlier chapters working in real contexts. (Healthcare, finance, and manufacturing examples appear throughout the book; the mechanics are identical.)
Sales is the most KPI-mature domain, and the most prone to gaming. The classic funnel KPI tree:
Revenue
├── Pipeline (leading)
│   ├── New opportunities created / week
│   └── Pipeline coverage ratio (target 3–4× quota)
├── Conversion (leading/lagging mix)
│   ├── Lead → opportunity conversion %
│   └── Opportunity → win rate % (target by segment)
└── Value (lagging)
    ├── Average deal size
    └── Sales cycle length (days; lower is better)
Core KPI set:
| KPI | Formula | Owner | Typical target | Gaming guard |
|---|---|---|---|---|
| Quota attainment % | Booked ÷ quota | Sales Director | 100% | Pair with discount rate |
| Pipeline coverage | Open pipeline ÷ quota | Sales Director | 3–4× | Audit stage definitions |
| Win rate % | Won ÷ (won + lost) | Sales Managers | varies by segment | Pair with deal-size trend |
| Avg discount % | Discount given ÷ list | Finance | ≤ 12% | The counterbalance KPI |
| Sales cycle (days) | Avg close − create | Sales Ops | −10% YoY | Watch for rushed closes |
The gaming story is instructive: quota attainment alone invites end-of-quarter discounting fire sales. The attainment + discount + win-rate trio is the defense — you can hit quota with 40% discounts, but you cannot hide it.
Quota Attainment % =
DIVIDE ( [Booked Revenue], SUM ( Quotas[QuotaAmount] ) )

Win Rate % =
DIVIDE (
    CALCULATE (
        DISTINCTCOUNT ( Opportunities[OppID] ),
        Opportunities[Stage] = "Closed Won"
    ),
    CALCULATE (
        DISTINCTCOUNT ( Opportunities[OppID] ),
        Opportunities[Stage] IN { "Closed Won", "Closed Lost" }
    )
)

Avg Discount % =
DIVIDE (
    SUM ( Opportunities[DiscountAmount] ),
    SUM ( Opportunities[ListAmount] )
)
Operations KPIs split into the classic triad — cost, quality, delivery — plus safety and productivity.
| KPI | Formula | Owner | Typical target |
|---|---|---|---|
| On-time delivery % | On-time orders ÷ total | Logistics Head | ≥ 98% |
| Order cycle time | Avg confirm→dispatch hours | Warehouse Mgr | ≤ 24h |
| Defect rate (DPMO or %) | Defects ÷ units | Quality Mgr | ≤ 1% / Six-Sigma bands |
| OEE % | Availability × Performance × Quality | Plant Mgr | ≥ 85% |
| Cost per unit | Total cost ÷ units | Ops Director | −3% YoY |
| Stockout rate % | Stockout SKUs ÷ SKUs | Inventory Mgr | ≤ 2% |
| LTIFR (safety) | Lost-time injuries × 1M ÷ hours worked | HSE Mgr | 0 |
Operations is where leading/lagging pairing shines: preventive-maintenance compliance (leading) → unplanned downtime (lagging); in-process quality checks (leading) → defect rate (lagging); carrier booking lead time (leading) → on-time delivery (lagging).
On-Time Delivery % =
DIVIDE (
    CALCULATE (
        COUNTROWS ( Shipments ),
        Shipments[DeliveredOnTime] = TRUE ()
    ),
    COUNTROWS ( Shipments )
)

OEE % =
    [Availability %] * [Performance %] * [Quality %]

Cost Per Unit =
DIVIDE (
    SUM ( CostLedger[TotalCost] ),
    SUM ( Production[UnitsProduced] )
)
HR KPIs measure the workforce as the organization's engine — hiring, capability, engagement, and retention.
| KPI | Formula | Owner | Typical target |
|---|---|---|---|
| Time to fill (days) | Avg requisition→accept | Talent Lead | ≤ 45 days |
| Quality of hire | Hiring-manager rating at 6 mo | HR Director | ≥ 4/5 |
| Voluntary turnover % | Voluntary leavers ÷ avg headcount | HR Director | ≤ 8–10% |
| Regretted attrition % | High-performer leavers ÷ high performers | HR Director | ≤ 5% |
| eNPS | % promoters − % detractors | HR Director | ≥ +30 |
| Training completion % | Completed ÷ assigned | L&D Mgr | ≥ 95% |
| Absenteeism % | Absent days ÷ scheduled days | HR Ops | ≤ 3% |
HR's gaming risk is subtle: turnover looks great if you stop hiring (denominator games) or reclassify leavers. Hence regretted attrition (losing people you wanted to keep) as the honest KPI, and eNPS as the leading pulse.
Voluntary Turnover % =
DIVIDE (
    CALCULATE (
        DISTINCTCOUNT ( Separations[EmployeeID] ),
        Separations[Type] = "Voluntary"
    ),
    AVERAGE ( Headcount[Headcount] )
)

eNPS =
VAR Promoters =
    DIVIDE (
        CALCULATE (
            COUNTROWS ( EngagementSurvey ),
            EngagementSurvey[Score] >= 9
        ),
        COUNTROWS ( EngagementSurvey )
    )
VAR Detractors =
    DIVIDE (
        CALCULATE (
            COUNTROWS ( EngagementSurvey ),
            EngagementSurvey[Score] <= 6
        ),
        COUNTROWS ( EngagementSurvey )
    )
RETURN
    Promoters - Detractors
Education KPIs serve students, faculty, administrators, and regulators — each with different definitions of success, which is why the KPI spec (Chapter 1) matters most here.
| KPI | Formula | Owner | Typical target |
|---|---|---|---|
| Application→enrollment yield % | Enrolled ÷ admitted | Admissions Dir | ≥ 30% |
| First-year retention % | Returning ÷ cohort | Dean | ≥ 85% |
| On-time graduation % | Graduated on time ÷ cohort | Dean | ≥ 70% |
| Graduate employment % (6 mo) | Employed ÷ graduates | Careers Office | ≥ 80% |
| Student satisfaction % | Satisfied ÷ respondents | Quality Office | ≥ 85% |
| Faculty:student ratio | FTE faculty ÷ FTE students | Provost | ≤ 1:20 |
| Research income per faculty | Grant income ÷ faculty | Research Dean | +10% YoY |
Education's classic tension: access vs outcomes. Widening access (more admits) can depress graduation rates — so these KPIs must be read as a set, segmented by entry pathway, never as a single headline. The leading indicators from Chapter 4 (week-4 submission rates, advising contacts) belong on the operational dashboard that deans review monthly.
First-Year Retention % =
DIVIDE (
    CALCULATE (
        DISTINCTCOUNT ( Enrollments[StudentID] ),
        Enrollments[AcademicYear] = "Year 2"
    ),
    DISTINCTCOUNT ( Cohorts[StudentID] )
)

Graduate Employment % =
DIVIDE (
    CALCULATE (
        COUNTROWS ( AlumniSurvey ),
        AlumniSurvey[Employed6Mo] = TRUE ()
    ),
    COUNTROWS ( AlumniSurvey )
)
Healthcare KPIs carry a moral weight other domains do not: the "defects" are human harm. The field organizes KPIs around the triple aim — better patient experience, better population health, lower cost — which maps neatly onto the Balanced Scorecard.
| KPI | Formula | Owner | Typical target |
|---|---|---|---|
| Avg length of stay (ALOS) | Patient-days ÷ discharges | Medical Director | Benchmark-adjusted |
| 30-day readmission % | Readmitted ÷ discharges | Quality Officer | ≤ national benchmark |
| Hospital-acquired infection rate | Infections ÷ 1,000 patient-days | Infection Control | trending down |
| ED wait time (triage→doctor) | Avg minutes | ED Head | ≤ 30 min |
| Bed occupancy % | Occupied bed-days ÷ available | Ops Manager | 85–90% (full is unsafe) |
| Mortality ratio (HSMR/RAMI) | Observed ÷ expected deaths | Medical Director | ≤ 100 |
| Patient satisfaction % | Top-box ÷ respondents | Patient Experience | ≥ 85% |
Two subtleties matter. First, risk adjustment: raw mortality or readmission rates punish hospitals that take sicker patients — always compare observed vs expected (adjusted for case mix), never raw rates across hospitals. Second, occupancy targets are bands, not maxima: 100% occupancy means no surge capacity and soaring infection risk; the KPI is green inside 85–90%, amber outside either way — a rare two-sided threshold.
Readmission Rate % =
DIVIDE (
    CALCULATE (
        DISTINCTCOUNT ( Discharges[PatientID] ),
        Discharges[Readmitted30d] = TRUE ()
    ),
    DISTINCTCOUNT ( Discharges[PatientID] )
)

Bed Occupancy % =
DIVIDE (
    SUM ( BedDays[OccupiedDays] ),
    SUM ( BedDays[AvailableDays] )
)
Banks live under regulators, so their KPI sets blend business performance with risk and compliance — a useful model for any regulated industry.
| KPI | Formula | Owner | Typical target |
|---|---|---|---|
| Net interest margin % | (Interest income − expense) ÷ earning assets | CFO | ≥ peer median |
| Cost-to-income ratio % | Operating cost ÷ operating income | CFO | ≤ 50% |
| NPL ratio % | Non-performing loans ÷ total loans | Chief Risk Officer | ≤ internal limit |
| Capital adequacy (CAR) % | Capital ÷ risk-weighted assets | CRO | ≥ regulatory min + buffer |
| Loan-to-deposit ratio % | Loans ÷ deposits | Treasurer | 80–90% |
| Digital adoption % | Active digital users ÷ customers | CDO | +10pp YoY |
| Complaint resolution (days) | Avg days to close | Service Head | ≤ 7 days |
The design lesson: risk KPIs are constraints, not goals — NPL ratio and CAR have ceilings/floors, and breaching them triggers mandatory action (regulatory, not optional). In your KPI dictionary, tag each KPI as goal-type (maximize/minimize toward target) or constraint-type (stay within bounds). Dashboards should visually distinguish them: constraints get hard red lines; goals get RAG bands.
NPL Ratio % =
DIVIDE (
    CALCULATE (
        SUM ( Loans[Outstanding] ),
        Loans[Status] = "Non-performing"
    ),
    SUM ( Loans[Outstanding] )
)

Cost to Income % =
DIVIDE (
    SUM ( GL[OperatingCost] ),
    SUM ( GL[OperatingIncome] )
)
Across all six domains in this chapter, the same four questions recur — and they form a starter set for any organization designing KPIs from scratch:
Start here — one or two KPIs per question, each with the full spec — then add domain-specific depth. This is the Balanced Scorecard (Chapter 3) in practical form, and it prevents the most common beginner error: a KPI set that is 90% financial and 100% lagging. If your draft set cannot answer all four questions, it is not a picture of the business; it is a picture of the finance department.
For your research: If your thesis touches any of these domains, this chapter is a source of validated, real-world variables — and a warning. Using "employee turnover" as a variable without specifying voluntary vs involuntary, or "student performance" without defining the assessment and cohort, repeats the incomparable-definitions anti-pattern (Chapter 2) inside your research. Borrow the domain's standard definitions, cite them, and put your full operational definitions in an appendix table modeled on the KPI specification. Reviewers in applied fields will recognize the rigor immediately.
Key takeaways:
- Each domain has a classic KPI set — learn your domain's canon before inventing new indicators.
- Sales: guard attainment with discount and win-rate counterbalances. Operations: pair leading process KPIs with lagging outcome KPIs. HR: prefer regretted attrition over raw turnover. Education: read access and outcome KPIs as a segmented set.
- The DAX patterns repeat across domains: DIVIDE ratios, CALCULATE filters, survey-score math — master the pattern once, apply everywhere.
Here is the chapter that turns the whole book inward. A thesis or research project is a production system: it has inputs (reading, data), processes (experiments, analysis, writing), outputs (chapters, papers), and a deadline. Yet most researchers manage it by anxiety — a vague sense of falling behind, discovered too late. Apply everything in this book to the project itself, and you get something rare: a researcher who can see trouble coming while there is still time to act.
Start with Chapter 3's process. Goal: "Submit a defensible thesis by [date] with at least one publication submitted." Critical success factors: literature mastery, data/experiments complete, analysis sound, writing finished, supervisor alignment. Now design KPIs per CSF — a mix of leading and lagging, each with a target, a rhythm, and an owner (you, plus your supervisor as stakeholder).
Literature mastery (leading): - Papers read deeply per week — target 3–5. "Deeply" means summarized in your literature table (Book 1's Author|Objective|Method|Finding|Limitation row), not skimmed. - Literature table coverage — % of your planned core papers summarized. Target 100% by end of month 2. - Lagging partner: related-work chapter draft complete (yes/no by date).
Experiments/data (leading + lagging): - Experiments completed per week — target 2 (Chapter 4's advice). Owner: you. Red (< 1 for two weeks) triggers a supervisor meeting — the "action on red." - Dataset readiness % — collected, cleaned, labeled, split. Track as a checklist percentage. - Blocked days — days waiting on data access, compute, or ethics approval. Leading indicator of schedule risk; if it exceeds 10, escalate. - Lagging partner: results chapter draft complete.
Writing (the KPI researchers avoid): - Draft pages per week — target 4–6 during writing phase. Writing is the ultimate lagging indicator of thinking; a page target makes it visible early. - Supervisor feedback cycle time — days from draft sent to comments received. If this drifts past 14, the bottleneck is not you — raise it. - Revision rounds per chapter — more than 3 suggests the chapter's argument was unclear; a quality signal.
Publication pipeline (lagging, with leading feeders): - Papers submitted / in review / revise-and-resubmit / accepted — a funnel, exactly like the sales pipeline in Chapter 10. Pipeline coverage for researchers: submissions in flight should be ≥ 2× your target publications. - Conference deadlines hit % — deadlines met ÷ deadlines targeted. Missed deadlines are the research equivalent of lost deals.
Every Monday, 30 minutes, with a one-page dashboard — even a spreadsheet:
| KPI | Target | Actual | RAG | Action |
|---|---|---|---|---|
| Papers summarized (wk) | 4 | 2 | 🔴 | 2 catch-up sessions booked |
| Experiments (wk) | 2 | 2 | 🟢 | — |
| Draft pages (wk) | 5 | 6 | 🟢 | — |
| Blocked days (cumul.) | ≤ 10 | 12 | 🟡 | Emailed lab for GPU slot |
| Next milestone | 15 Oct | On track | 🟢 | — |
(Use text labels alongside color — Chapter 6's accessibility rule applies to your spreadsheet too.)
Bring this to supervision meetings. Supervisors consistently report that students who arrive with a status page get better guidance — because the meeting starts from facts, not feelings. You are also demonstrating the professional skill this whole book teaches, in the context where it matters most to your career.
Apply Chapter 6 honestly: set milestone dates by bottom-up capacity (how many pages/experiments can you really do per week? check against your last month's actuals — the historical baseline method) plus top-down requirement (the submission deadline, minus buffer). Set the amber threshold at 1 week of slippage, red at 2 — and define the action on red in advance: "two red weeks → supervision meeting within 5 days." Deciding the response before the crisis is the entire point of thresholds.
If you keep a simple log table (ResearchLog with Date, Activity, Hours, OutputType), these measures build your personal dashboard:
Papers Summarized (Week) =
CALCULATE (
    COUNTROWS ( ResearchLog ),
    ResearchLog[Activity] = "Paper summary",
    DATESMTD ( 'Date'[Date] )
)

-- Replace DATESMTD with a 7-day window for true weekly tracking:
Papers Summarized (7d) =
CALCULATE (
    COUNTROWS ( ResearchLog ),
    ResearchLog[Activity] = "Paper summary",
    DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ), -7, DAY )
)

Writing Pace (Pages/Week) =
DIVIDE (
    CALCULATE (
        SUM ( ResearchLog[PagesWritten] ),
        DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ), -7, DAY )
    ),
    1
)

Research RAG =
VAR Pace = [Writing Pace (Pages/Week)]
RETURN
    SWITCH (
        TRUE (),
        Pace >= 5, "Green",
        Pace >= 3, "Amber",
        "Red"
    )
Is this overkill? For some, yes — a spreadsheet works. But building it teaches you the full KPI lifecycle (design → DAX → dashboard → review) on a dataset you care about, which is the best possible practice for the professional work in Chapter 12.
Your supervisor is the executive sponsor of your research KPI system — and like any sponsor, they need a contract, not assumptions. Agree explicitly, early:
Write it down — one page, both sign. Students resist this as overly formal; supervisors almost universally welcome it, because it replaces vague anxiety with a professional operating rhythm. It is also, quietly, evidence of research maturity that external examiners love to see referenced in the methodology chapter.
Every project has known risks; researchers just rarely write them down. Keep a risk register — a table of the top 5–8 risks, each with a leading indicator, a threshold, and a contingency:
| Risk | Leading indicator | Amber trigger | Contingency |
|---|---|---|---|
| Dataset access delayed | Blocked days | > 7 | Switch to public backup dataset |
| GPU/compute unavailable | Queue wait hours | > 48h avg | Reduce experiment grid; use colab fallback |
| Supervisor unresponsive | Feedback cycle days | > 14 | Proceed on written assumptions; escalate to co-supervisor |
| Scope creep | Open research questions count | > 5 | Freeze scope; park extras in future work |
| Writing stall | Pages/week | < 3 for 2 wks | Daily 500-word sprints; writing group |
Review the register monthly. Most thesis crises — the lost semester, the failed experiment campaign — were visible in a leading indicator weeks earlier. The register is how you make sure you look.
When your thesis is done, the tracking system from this chapter becomes methodology content. A compact write-up template:
"Project progress was monitored using a KPI framework adapted from Parmenter (2019). Six KPIs were defined — three leading (papers summarized per week, experiments completed per week, draft pages per week) and three lagging (literature review completion, results chapter completion, submissions in the publication funnel) — each with targets, weekly review, and pre-agreed escalation actions. The full KPI specification table is provided in Appendix C. Two red episodes occurred (weeks 9–10, experiments blocked by compute availability); the escalation protocol triggered a scope reduction documented in the research log."
That paragraph does triple duty: it demonstrates project management rigor, it cites established literature for an unconventional choice, and it shows honest reporting of problems — exactly what examiners reward. Keep the weekly status tables as evidence; a single appendix page of RAG history is more convincing than a paragraph claiming "the project proceeded smoothly." Start this week: define your six KPIs tonight, and hold your first Monday review next week.
A concrete plan for one semester of thesis work, showing targets, rhythm, and escalation:
| Weeks | Phase | Leading KPIs (weekly targets) | Lagging milestone | Red trigger → action |
|---|---|---|---|---|
| 1–3 | Literature | 4 paper summaries/wk; table 100% of 30 core papers by wk 3 | Related-work outline approved | < 3 summaries/wk for 2 wks → daily 90-min reading blocks |
| 4–6 | Data/pilot | Dataset readiness 100% by wk 6; 1 pilot experiment/wk | Pilot results reviewed | Blocked days > 7 → switch to backup dataset |
| 7–11 | Experiments | 2 experiments/wk; results logged same-day | Results chapter draft (wk 11) | < 1 experiment/wk for 2 wks → supervision meeting in 5 days |
| 12–14 | Writing | 5 draft pages/wk | Full draft to supervisor (wk 14) | < 3 pages/wk for 2 wks → writing group + daily sprints |
| 15–16 | Revision | Feedback cycle ≤ 10 days; revision rounds ≤ 2/chapter | Submission-ready thesis | Feedback > 14 days → proceed on written assumptions |
Notice the structure: every phase has leading KPIs with weekly targets, one lagging milestone, and a pre-agreed red trigger with a named action. Copy this table, adjust the numbers to your reality (bottom-up capacity, top-down deadline — Chapter 6), and you have a supervision-ready plan in one page.
For your research: This chapter is the "for your research" box, expanded. The deeper point: your thesis methodology can cite KPI-design literature. When you justify your progress-tracking or your evaluation framework, references like Parmenter (KPIs) and Kaplan & Norton (Balanced Scorecard) are legitimate, peer-recognized sources — they turn "I kept a to-do list" into "progress was monitored using a KPI framework adapted from Parmenter (2019)." That single sentence elevates a mundane project-management paragraph into a methodologically grounded one. Examiners notice.
Key takeaways: - Manage your thesis like a production system: KPIs for literature, experiments, writing, and the publication funnel — leading and lagging, with targets and review rhythms. - The Monday 30-minute review with a one-page RAG status page is the highest-ROI habit in this chapter. - Set milestone targets bottom-up (your real capacity) constrained top-down (the deadline), with pre-agreed actions for red. - A Power BI research tracker is both a productivity tool and the best practice ground for professional KPI skills.
You have the theory. This capstone walks you through building a complete KPI dashboard end to end — from a fictional company's messy reality to a governed, reviewed dashboard. Follow along in Power BI Desktop; every step maps to a chapter in this book. The company is fictional, but every decision below mirrors real projects.
Northwind Traders sells specialty foods online and through regional stores. The CEO's strategy for the year: "Profitable growth — grow revenue 15% while holding gross margin at 40%." The CFO adds a constraint: keep operating costs flat. You are the analyst. Deliverable: a KPI dashboard the executive team reviews monthly, plus an operational page the sales and logistics managers review weekly.
Goal → CSFs → candidates → selection:
Six KPIs — inside the 5–10 guideline. Each gets a spec (owner, frequency, thresholds, action on red). Leading indicators for the operational page: pipeline coverage (sales), orders picked per hour (warehouse), carrier booking lead time (logistics).
Tables: Sales (fact: OrderID, Date, Region, Product, Amount, Cost, Discount), Targets (YearMonth, Region, TargetRevenue, TargetMargin), OpexBudget (Month, Dept, Budget, Actual), Shipments (OrderID, PromisedDate, ActualDate), Date (proper date table, marked as date table).
Relationships: Date[Date] → Sales[Date], Shipments[ActualDate]; Targets bridged to Date via TREATAS on YearMonth (Chapter 8). Check quality: reconciliation measure comparing dashboard revenue to finance's GL export; "Data as of" card from MAX(Sales[LoadDate]).
Build the full family. Base and targets:
Total Revenue = SUM ( Sales[Amount] )
Total Cost = SUM ( Sales[Cost] )
Gross Profit = [Total Revenue] - [Total Cost]

Gross Margin % = DIVIDE ( [Gross Profit], [Total Revenue] )

Target Revenue =
CALCULATE (
    SUM ( Targets[TargetRevenue] ),
    TREATAS ( VALUES ( 'Date'[YearMonth] ), Targets[YearMonth] )
)
Time intelligence and attainment:
Revenue YTD = CALCULATE ( [Total Revenue], DATESYTD ( 'Date'[Date] ) )
Target Revenue YTD = CALCULATE ( [Target Revenue], DATESYTD ( 'Date'[Date] ) )
Revenue Attainment % = DIVIDE ( [Revenue YTD], [Target Revenue YTD] )
Revenue PY = CALCULATE ( [Total Revenue], SAMEPERIODLASTYEAR ( 'Date'[Date] ) )
Revenue YoY % = DIVIDE ( [Total Revenue] - [Revenue PY], [Revenue PY] )
Driver decomposition (the margin tree):
Avg Discount % = DIVIDE ( SUM ( Sales[DiscountAmount] ), SUM ( Sales[ListAmount] ) )

-- Margin tree: Gross Margin % = f(discount, product mix, unit cost)
Discount Impact on Margin =
    ( [Avg Discount %] - [Target Discount %] ) * -1
RAG and status:
Revenue RAG =
VAR A = [Revenue Attainment %]
RETURN
    SWITCH (
        TRUE (),
        ISBLANK ( A ), "No data",
        A >= 1, "Green",
        A >= 0.95, "Amber",
        "Red"
    )

Margin RAG =
VAR M = [Gross Margin %]
RETURN
    SWITCH (
        TRUE (),
        ISBLANK ( M ), "No data",
        M >= 0.40, "Green",
        M >= 0.38, "Amber",
        "Red"
    )

Revenue RAG Color =
SWITCH (
    [Revenue RAG],
    "Green", "#2E7D32",
    "Amber", "#F9A825",
    "Red", "#C62828",
    "#9E9E9E"
)
Put measures in display folders (Base / Time Intelligence / Targets & Variance / RAG & Status), write one-line descriptions, set format strings.
Page 1 — Executive KPI summary (monthly): KPI card strip across the top (Revenue attainment, Revenue YoY, Gross margin %, Avg discount %, On-time delivery %, Opex variance %) — each card: value, target, variance, RAG dot + label, 12-month sparkline. Below: trend+target line charts for revenue and margin. Bottom: exception table — regions/products with red or amber status, sorted by shortfall impact. One page, no scroll.
Page 2 — Driver analysis: the revenue tree (orders × AOV decomposition) and margin waterfall (target margin → discount impact → mix impact → actual). Decomposition Tree visual for interactive drill-down by region and product category.
Page 3 — Operational (weekly): leading indicators — pipeline coverage gauge (bullet graph), orders picked per hour trend, carrier lead-time trend, this week's exception list. Slicers: region, week.
Mobile layout: page 1 condensed — six cards stacked, two key trends.
Month 3: Revenue attainment shows Amber, 96%. The exception table points at the West region. Driver page: orders on target, AOV down 6% → discount deeper than plan in West. Decision logged: West regional manager to tighten discount approvals above 12%; review in 30 days. Month 4: attainment back to Green, 101%. That — a red/amber that triggered a named action that moved the number — is the entire point of this book. Everything else was scaffolding.
The dashboard is built; now you must sell it in the room. Rules for the first review:
Dashboards rot. Targets set this year mislead next year; data sources change; the strategy pivots. Write the maintenance plan now:
Budget for maintenance explicitly — roughly 15–20% of the build effort per year. A dashboard with no maintenance budget is a dashboard with an expiry date.
Finished the core build? These extensions each teach a professional skill:
Each extension is a portfolio piece on its own — and together they cover the skill set employers test for in BI analyst interviews.
Close the capstone with a one-page sign-off, signed by the executive sponsor and each KPI owner:
A dashboard without sign-off is a prototype; the signatures convert it into an organizational commitment — which is what makes the reds get acted on in month 3 instead of admired.
For your research: Treat this capstone as a methods template for any applied thesis with a dashboard component — and as a portfolio piece. A thesis chapter that walks through design → data model → measures → layout → governance, with the checklist as your validation section, is structured exactly like a design-science research contribution. Even better: document one real review cycle (the Month 3 → Month 4 story above, with real numbers from your own research tracker in Chapter 11) as evidence that the artifact works. "We built it, we used it, here is what changed" is the strongest claim an applied researcher can make.
Key takeaways: - A complete KPI dashboard = designed KPIs + clean model + governed DAX + five-second layout + alerts/subscriptions + a review meeting where decisions happen. - Build in layers: executive summary, driver analysis, operational detail — plus mobile. - The dashboard is scaffolding; the value is the decision log. If no decision changed, the dashboard failed regardless of how beautiful it is. - Use the 8-point checklist before calling any KPI dashboard done.
| Block | Prompt | Your answer |
|---|---|---|
| Strategic goal | Which goal does this serve? (Chapter 3) | |
| Critical success factor | What must go right? | |
| KPI name | Short, unambiguous | |
| Definition | Computable by a stranger (Chapter 1) | |
| Formula | Exact calculation | |
| Unit & direction | %, $, days… / higher or lower is better? | |
| Data source | Table, column, system | |
| Owner | Named person | |
| Frequency | Measured / reviewed | |
| Target | Value + rationale (Chapter 6) | |
| Thresholds | Green / Amber / Red bands | |
| Leading or lagging | And its paired indicator (Chapter 4) | |
| Parent in KPI tree | Which headline KPI does it drive? (Chapter 5) | |
| Action on red | Named response within a deadline | |
| Counterbalance KPI | What stops gaming? (Chapter 2) | |
| Review date | Next design review |
| Step | Rule of thumb |
|---|---|
| Set the target first | Document the rationale: baseline, benchmark, top-down, or bottom-up (Chapter 6) |
| Direction | State explicitly whether higher or lower is better — thresholds flip |
| Amber width | Start at ~1 standard deviation of normal variation, or 2–5% around target |
| Calibrate from history | If red fired > 25–30% of recent periods, widen bands or fix the target — not the process |
| Noisy KPIs | Require 2 consecutive breaches or a 3-period average before flagging (hysteresis) |
| Always pair | Color + value + target + variance; never color alone |
| Accessibility | Add icons or text labels — ~1 in 12 men has color-vision deficiency |
| Govern the logic | Thresholds live in DAX (SWITCH(TRUE(),...)), not in visual settings |
| Pattern | DAX skeleton | Chapter |
|---|---|---|
| Base measure | Total X = SUM ( Fact[Column] ) |
1 |
| Safe ratio | DIVIDE ( [Numerator], [Denominator] ) |
1 |
| Attainment % | DIVIDE ( [Actual], [Target] ) |
1 |
| YTD / MTD / QTD | CALCULATE ( [M], DATESYTD ( 'Date'[Date] ) ) |
8 |
| Prior year | CALCULATE ( [M], SAMEPERIODLASTYEAR ( 'Date'[Date] ) ) |
8 |
| Prior month/quarter | CALCULATE ( [M], DATEADD ( 'Date'[Date], -1, MONTH ) ) |
8 |
| YoY / MoM % | DIVIDE ( [M] - [M Prior], [M Prior] ) |
8 |
| Variance | [M] - [Target M] and DIVIDE ( [Variance], [Target M] ) |
8 |
| Rolling 12M | CALCULATE ( [M], DATESINPERIOD ( 'Date'[Date], MAX ( 'Date'[Date] ), -12, MONTH ) ) |
8 |
| Moving average | AVERAGEX ( DATESINPERIOD ( ... -3, MONTH ), [M] ) |
8 |
| RAG status | SWITCH ( TRUE(), ISBLANK(A), "No data", A >= 1, "Green", A >= 0.95, "Amber", "Red" ) |
6 |
| RAG color (field value) | SWITCH ( [RAG], "Green", "#2E7D32", "Amber", "#F9A825", "Red", "#C62828", "#9E9E9E" ) |
6 |
| Status score (sortable) | SWITCH ( TRUE(), ..., 3, ..., 2, 1 ) |
8 |
| Alert trigger | IF ( [Attainment %] < 0.95, 1, 0 ) |
9 |
| Unrelated targets bridge | CALCULATE ( SUM ( Targets[Amt] ), TREATAS ( VALUES ( 'Date'[YM] ), Targets[YM] ) ) |
8 |
| Data freshness | MAX ( Fact[LoadDate] ) |
9 |
| Missing days | COUNTROWS ( EXCEPT ( DATESINPERIOD(...), VALUES ( Fact[Date] ) ) ) |
9 |
| Driver contribution | ( [Child] - [Child Target] ) * [Sibling Target ] |
5 |
Sales[Amount], Sales[OrderDate], a Date table, and a Targets table (YearMonth, TargetAmount): write measures for (a) Revenue YTD, (b) Revenue PY, (c) Revenue YoY %, (d) Revenue YTD attainment %, (e) a RAG status measure with 100%/95% bands, and (f) its hex-color companion measure.[1] S. Few, Information Dashboard Design: Displaying Data for At-a-Glance Monitoring, 2nd ed. Sebastopol, CA, USA: O'Reilly Media, 2013.
[2] S. Few, Now You See It: Simple Visualization Techniques for Quantitative Analysis. Burlingame, CA, USA: Analytics Press, 2009.
[3] D. Parmenter, Key Performance Indicators: Developing, Implementing, and Using Winning KPIs, 4th ed. Hoboken, NJ, USA: Wiley, 2019.
[4] R. S. Kaplan and D. P. Norton, The Balanced Scorecard: Translating Strategy into Action. Boston, MA, USA: Harvard Business School Press, 1996.
[5] R. S. Kaplan and D. P. Norton, "The balanced scorecard — measures that drive performance," Harvard Business Review, vol. 70, no. 1, pp. 71–79, Jan./Feb. 1992.
[6] W. W. Eckerson, Performance Dashboards: Measuring, Monitoring, and Managing Your Business, 2nd ed. Hoboken, NJ, USA: Wiley, 2010.
[7] R. Kimball and M. Ross, The Data Warehouse Toolkit: The Definitive Guide to Dimensional Modeling, 3rd ed. Hoboken, NJ, USA: Wiley, 2013.
[8] A. Ferrari and M. Russo, The Definitive Guide to DAX: Business Intelligence for Microsoft Power BI, SQL Server Analysis Services, and Excel, 2nd ed. Redmond, WA, USA: Microsoft Press, 2019.
[9] E. R. Tufte, The Visual Display of Quantitative Information, 2nd ed. Cheshire, CT, USA: Graphics Press, 2001.
[10] E. Ries, The Lean Startup: How Today's Entrepreneurs Use Continuous Innovation to Create Radically Successful Businesses. New York, NY, USA: Crown Business, 2011.
[11] T. H. Davenport and J. G. Harris, Competing on Analytics: The New Science of Winning. Boston, MA, USA: Harvard Business School Press, 2007.
[12] Microsoft, "Data Analysis Expressions (DAX) reference," Microsoft Learn. [Online]. Available: https://learn.microsoft.com/en-us/dax/
End of Book 28. Next: Book 29 — Power BI Visuals and Report Design.